
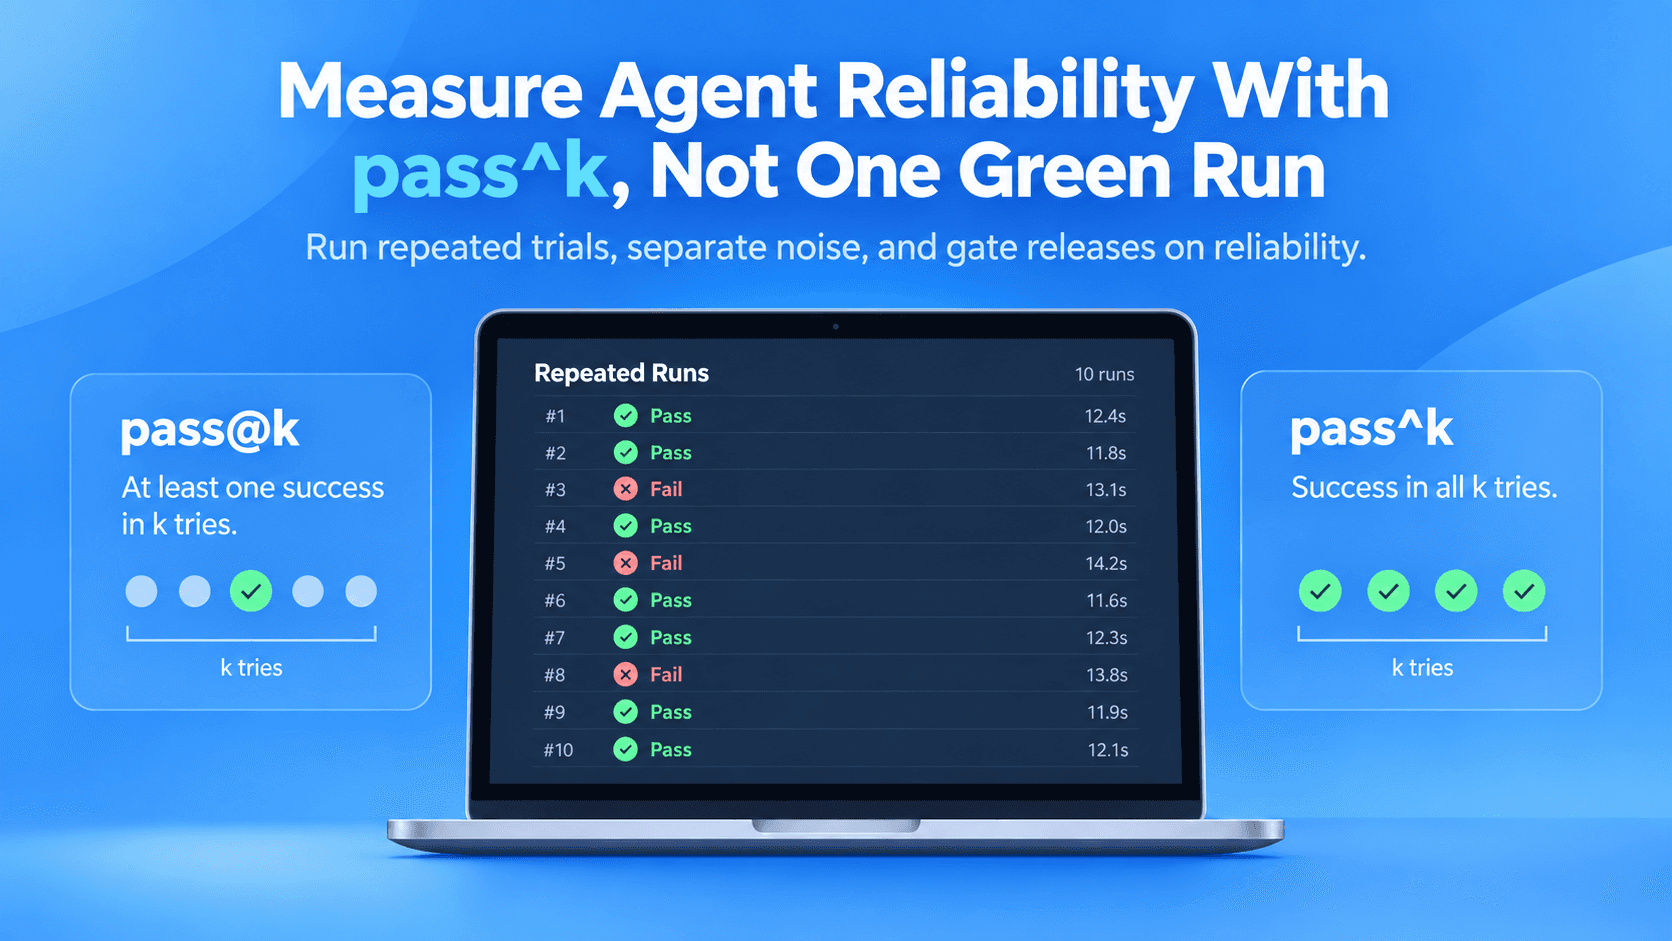
Measure Agent Reliability With pass^k, Not One Green Run
A single passing run shows an LLM agent can do a task, not that it will every time. How to run repeated trials, estimate pass@k and pass^k per task, separate grader and infrastructure noise, and pick the number that gates a release.