Lock Down a Self-Hosted LLM Server: Ollama and vLLM Defaults
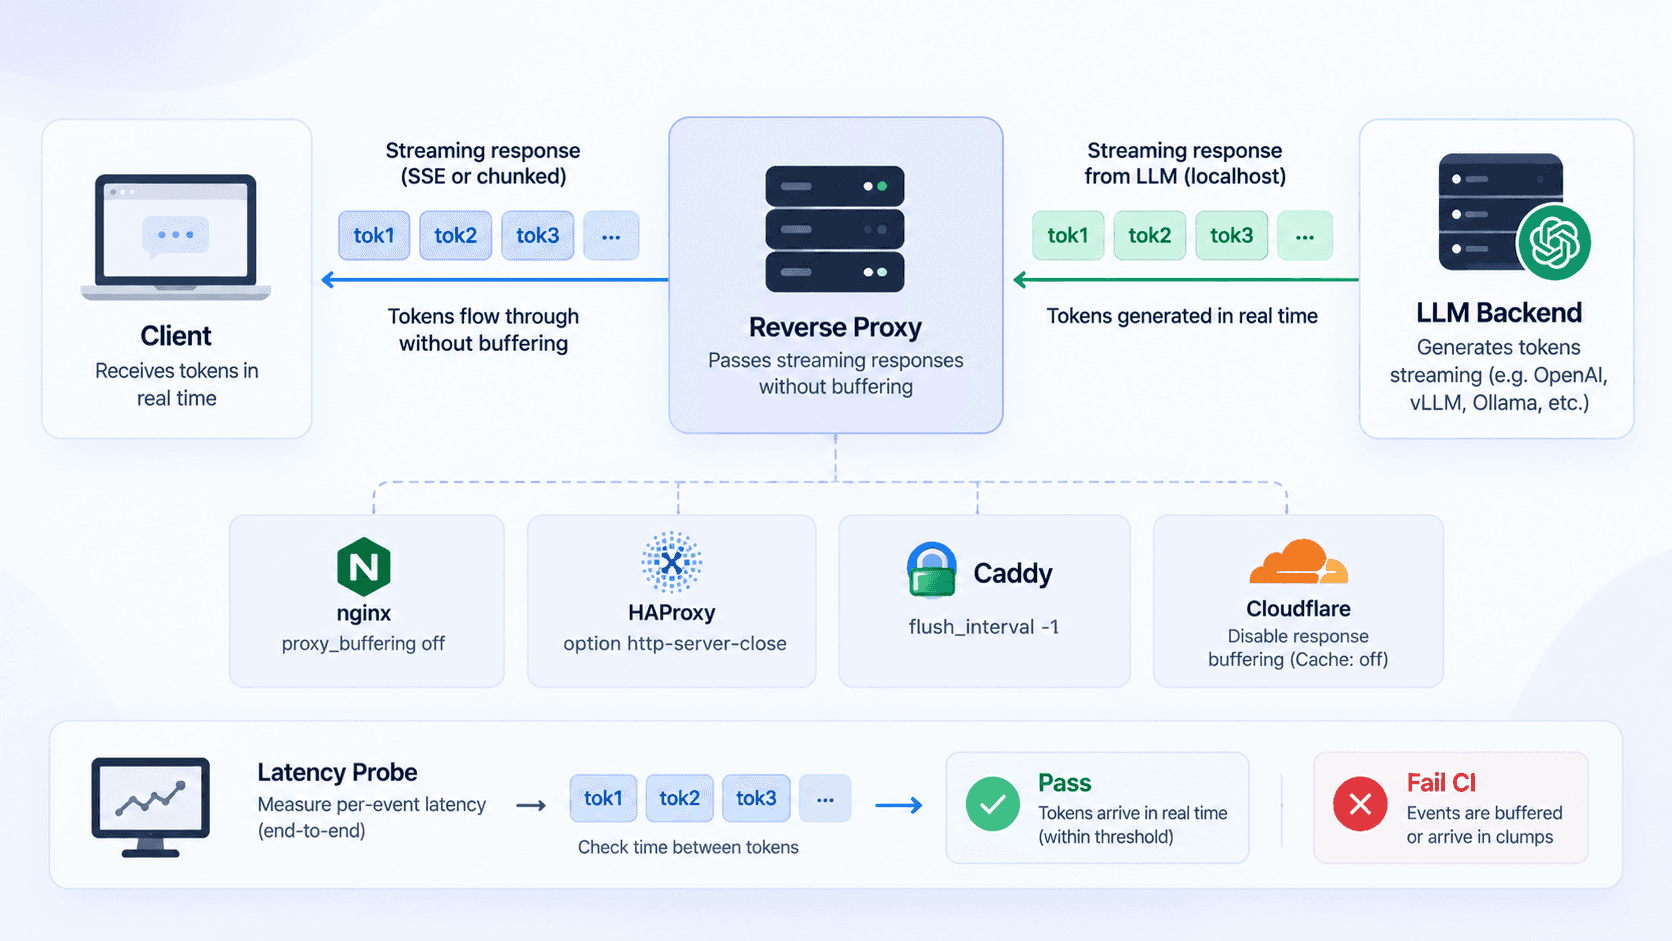
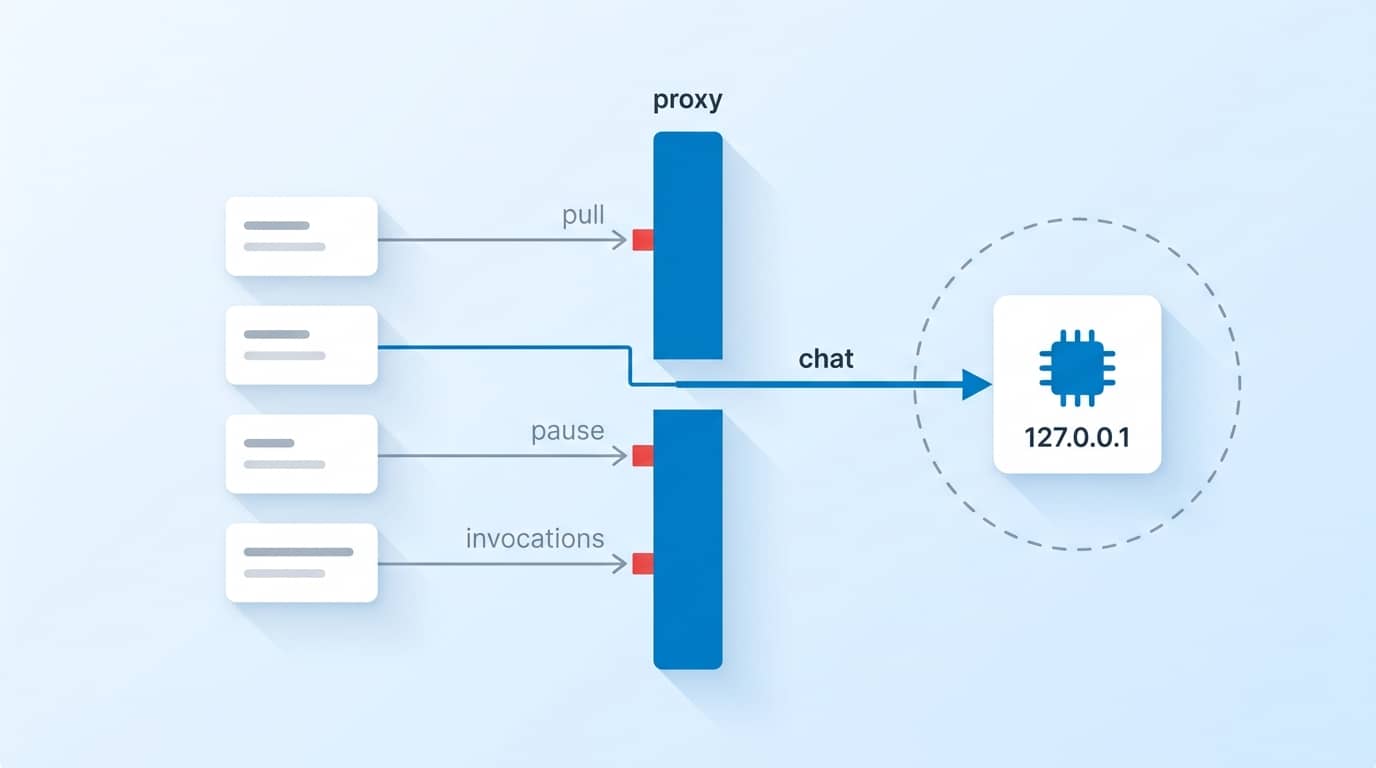
Ollama has no authentication for local requests, and vLLM’s --api-key covers only some paths. What an exposed inference server gives away, and the setup that closes it: loopback binding, an allowlisting proxy and closed ports.